Zod schema compilation: the 9x claim and the CSP catch
Zod schema compilation arrived in 4.5 with a 9x memory claim. See what it covers, how compile speed varies, and why a strict CSP quietly turns it off.
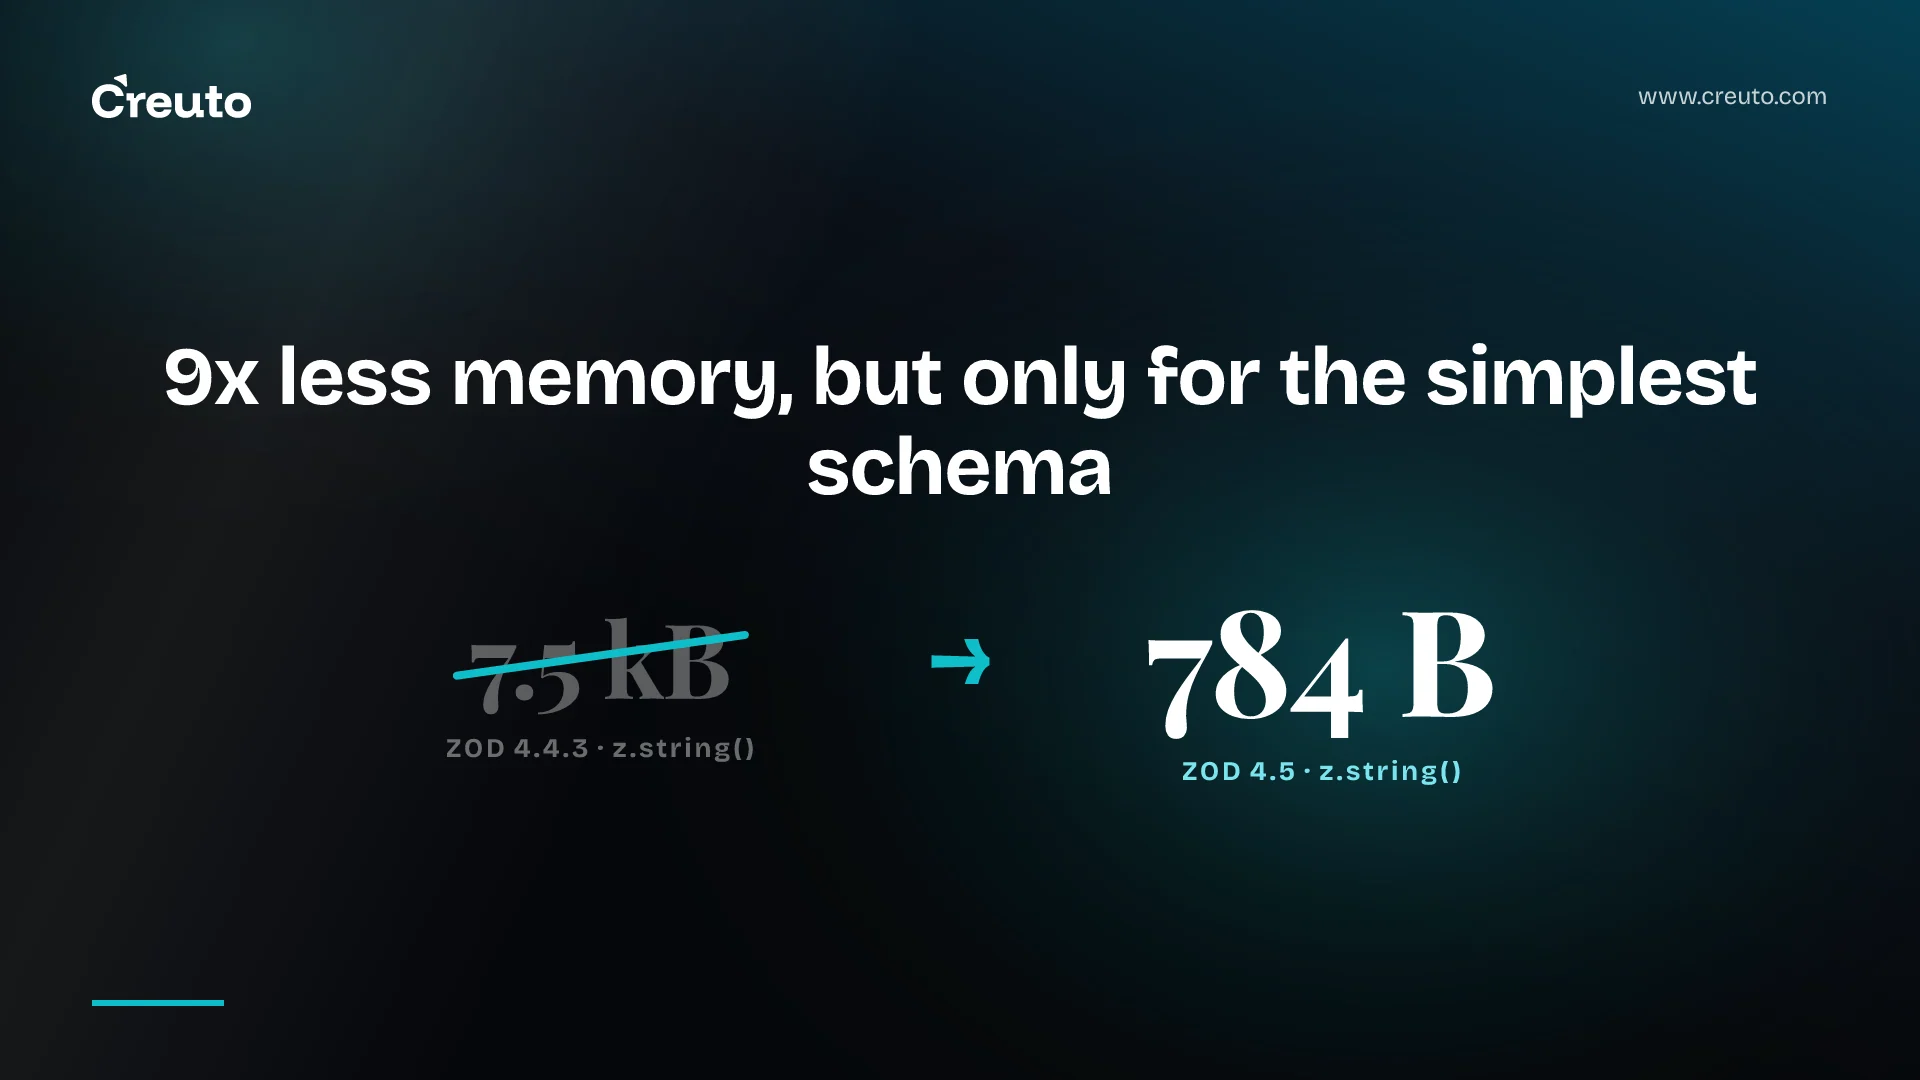
Zod schema compilation shipped in 4.5 next to a headline "9x" memory cut, and the two are separate changes. The 9x belongs to the simplest schema, z.string(). The memory saving arrives with the upgrade, while z.compile() is opt-in, speeds up valid input only, and quietly does nothing under a strict Content Security Policy.
Most coverage dropped those qualifiers. We read the Zod 4.5 release post, the 4.6 release post, the compile documentation and the InfoQ report side by side, then ran a small benchmark of our own. Figures are as of 20 October 2026.
Zod schema compilation and the memory cut are two separate changes
Zod 4.5 was released on 28 August 2026, 4.6 followed on 9 September, and InfoQ covered the pair on 16 October. InfoQ's headline joins compilation and the memory cut, which reads as if one causes the other. It does not.
The memory saving comes from what the author calls method memoization. In Zod 4.4 and earlier every schema method was bound to its instance, so a z.string() had 49 own properties. In 4.5 the methods are prototype getters that bind and cache themselves on first access, so a method you never call costs no heap. None of that involves z.compile().
In practice, upgrading gives you the memory and failure-path gains on every schema. Compilation speeds up valid input only on schemas you choose to compile, and adds code to your bundle.
The 9x figure is the best case, and the full table runs from 2.0x to 9.8x
Zod's own post says "In Zod 4.4 a bare z.string() retained 7.5kb of heap. In Zod 4.5 it retains 784 bytes." That is 9.8x on the project's benchmark table. The post's own heading says "9x reduction", and InfoQ calls it "roughly nine-fold". All three are fair for that one schema. Neither generalises, as the 27-row table in the memory write-up shows.
| Schema | Zod 4.4.3 | Zod 4.5 | Smaller by |
|---|---|---|---|
z.string() | 7.5 kB | 784 B | 9.8x |
z.union([...]), 2 options | 17.5 kB | 2.1 kB | 8.3x |
z.object({...}), 10 keys | 82.0 kB | 11.0 kB | 7.5x |
z.object({...}), 3 keys | 22.2 kB | 5.3 kB | 4.2x |
z.discriminatedUnion(...), 2 options | 42.0 kB | 12.7 kB | 3.3x |
z.object({}) | 6.6 kB | 3.3 kB | 2.0x |
Source: Zod, "Reducing Zod's memory footprint", retained heap per schema instance, Zod 4.4.3 versus 4.5. The post's chart gives the 10-key object as 7.4x where its table says 7.5x, so treat the second digit as rounding.
Here the sources diverge. An earlier summary we had been given described compound schemas as "6-8x". That range is in neither the Zod post nor InfoQ, so we cut it. Three-key objects fall 4.2x, discriminated unions 3.3x and an empty object only 2.0x. If your schemas are small objects, expect the middle of that range, not the headline.
What we measured ourselves
We installed Zod 4.4.3, 4.5.0 and 4.6.7 from npm on Node v22.22.3 (Apple M2, macOS), forced garbage collection, and measured the heap delta across 2,000 instances. A bare z.string() went from 7,510 B to 835 B on 4.5.0, which is 9.0x, and to 726 B on 4.6.7. A 10-key object of our own shape (seven strings, two numbers, one boolean) went from 67,201 B to 9,991 B, or 6.7x. These are not Zod's schemas or method, so they do not match its 82.0 kB, but the direction and rough size reproduce.
Compiled parsing is 2x to 10x faster, and InfoQ's tenfold quote is the top of that range
The release post says compilation speeds up objects, arrays and unions by a factor of about 3 to 9, and InfoQ repeats "three to nine times". Further down, InfoQ has developer Mehul Mohan describing "the roughly tenfold improvement on objects and arrays" as a real performance win. Those two statements do not describe the same thing. The compile documentation explains the gap: its per-schema scaling table measures each schema alone in a tight loop, which is "the standard parser's best case", so the ratios run lower than the headline chart.
| Schema measured alone | Compiled speedup |
|---|---|
| Object, 5 keys | 1.8x |
| Object, 10 keys | 2.2x |
| Object, 20 keys | 5.0x |
| Object, 50 keys | 10.2x |
Source: Zod, AOT compilation docs. The release post's headline chart shows a 20-key object going from 301 ns to 38 ns (7.8x), which is the top of a set of eight shapes.
Our run agrees with the docs' direction rather than the headline. On a 20-key object (13 strings, 7 numbers) with valid input, Zod 4.6.7 took about 144 ns per parse() uncompiled and 23 ns compiled, roughly 6x, over 300,000 iterations after a 50,000-iteration warm-up.
On the cross-library Moltar benchmark, Zod reports 47.5M operations per second compiled against 11.6M uncompiled for parseSafe, ahead of typia at 45.3M, Valibot at 1.8M and ArkType at 152k. That is about 4.1x by our arithmetic. For the boolean-only assertLoose category, compiled Zod reaches 60.6M and sits third behind typia at 74.9M and ArkType at 66.2M. InfoQ notes this too.
Compilation barely helps invalid input, so 4.6 added a separate tool
If a hot endpoint rejects a lot of bad requests, compilation is the wrong lever. The docs state that "Invalid inputs pay for both the fast path and the fallback, so compilation barely speeds up failures", because a compiled schema returns a sentinel and hands failures to the standard parser to build the error.
Two other changes cover failures. In 4.5, safeParse() no longer captures a stack trace on failure, which the release post says speeds failure-path parses by about 7.5x (6.3 microseconds to 840 nanoseconds in its chart) with no compile step. In 4.6, .validate() returns a boolean without building a ZodError, and combined with z.compile() it can be up to 35x faster than .safeParse().success on invalid input. InfoQ adds the right caution: that is a rejection check, not a general parsing speedup.
We saw the same pattern. On our 20-key schema with one wrong field, safeParse() took about 445 to 480 ns whether compiled or not, while validate() on the compiled schema took about 4 ns.
A strict CSP does not break z.compile(), it silently removes the speedup
The compiler works by generating a function. The docs say that "Compilation uses new Function, which is unavailable in CSP/no-eval environments", and the 4.6 post repeats that a strict Content Security Policy blocks it. Two behaviours follow from the docs. Setting z.config({ jitless: true }) stands down the global zod/compile mode. Calling z.compile() directly always attempts code generation, and where the environment refuses, "the schema comes back uncompiled like any other refusal".
So the failure mode is not an exception. It is a quiet return to the standard parser. We checked this with Node's --disallow-code-generation-from-strings flag, which makes new Function throw an EvalError. With the flag on, z.compile(schema) returned the very same schema object (compiled === original was true), threw nothing, and parsed at about 970 ns, against 23 ns compiled in the normal run. The flag also slowed the plain uncompiled parse, to about 960 ns from 144 ns. We did not investigate why, so do not read that as a rule.
That is a Node flag, not a browser CSP header, and we have not tested a browser. If you ship a strict CSP on a page that validates in the browser, assume the compile path is off until you have measured it there.
The fix Zod points to is z.withParser(), added in 4.6, which installs a parser generated somewhere else, at build time or by a native compiler. InfoQ is careful to say it does not generate that parser itself, so you would be writing or generating the fast path yourself.
Six schema features make compilation fall back or disappear
The docs list what cannot be compiled: async refinements, transforms and checks; z.xor(); recursive schemas; z.coerce.*; checks with a custom when; and .catch() with a callback. Inside an object, array, tuple, record or intersection, an unsupported child runs on the standard parser while the rest stays compiled. A union with an unsupported member, or anything async anywhere in the tree, makes the whole schema fall back. Passing { strict: true } throws instead, which confirms that a hot-path schema really compiled.
Ordering also trips people up. Methods like .refine() and .extend() return uncompiled schemas, so compile the final schema, not an intermediate. And import "zod/compile" must come before any module that defines a schema, so the docs offer node --import zod/compile app.js. It is for applications, not libraries.
The cost is bundle size. The docs put the compiler at about 7 KB gzipped, and in their four-key example Zod grows from 24.1 KB to 31.1 KB. If you never call z.compile() or import zod/compile, a bundler tree-shakes it out entirely. Before adding it to a client bundle, audit what your build ships.
Zod 4.5 breaking changes can reject input that used to pass
The 4.5 post files these under bug fixes and warns that a schema that relied on the old behavior may now reject input it used to accept. Three matter most for validation code:
- Datetimes need seconds.
z.iso.datetime()no longer accepts minute-precision input such as2020-01-01T06:15Z, because RFC 3339 mandates seconds.local: truestill allows2020-01-01T06:15. - String length counts code points.
.min(),.max()and.length()used to count UTF-16 code units, soz.string().max(5)rejected five emoji. The post says.max()only loosens, while.min()and.length()tighten for astral input. - A
__proto__key is always dropped by object and record parsers, wherever it comes from.
Test any datetime input that arrives at minute precision first, and any length bound applied to user-typed text. We have not hit these in client work. We are flagging them from the changelog.
Move to 4.6 rather than 4.5 if you validate recursive data
Per the 4.6 post, Zod 4.5 had a memory regression: a recursive schema held the input and output of its last parse, so one long-lived schema pinned every object it had touched, which surfaced as an out-of-memory failure on a repository-wide lint run. After the fix, one parse of a 29k-node tree retains 2.2 MB where it used to retain 10.1 MB, at a cost of about 6% parse speed for recursive schemas.
Recursive schemas cannot be compiled, so they get this fix and none of the compile speedup.
This is the wrong choice if your schemas are not on a hot path
Skip z.compile() when validation is not your bottleneck: a form that parses a few objects per interaction will not notice 144 ns becoming 23 ns. Skip it when your schemas lean on async refinements, transforms or recursion, when you ship a strict CSP, or when you publish a library. For most codebases the upgrade is the entire story.
Compilation earns its place on a server that validates large payloads at volume: big objects, long arrays, unions, and mostly valid input. Our own stack is TypeScript, React, Next.js and Node, and the Škoda Auto sales-training platform uses React, TypeScript and Node, but we have not run z.compile() in production, and everything above beyond our small benchmark comes from Zod's published figures. For a similar fast-with-caveats bargain, see our note on scriptc compiling TypeScript to native, and if you self-host Next.js, read the Next.js 16.3.8 self-hosting question alongside any dependency bump. Our web app development team runs this kind of dependency and performance review.
The decision to make this week is narrow. Upgrade to Zod 4.6 and run your tests against the datetime, string-length and __proto__ changes. Then pick one hot schema, compile it with strict: true in the environment that matches production, including your CSP, and compare against the uncompiled run before turning on zod/compile everywhere.
Frequently asked questions
Zod schema compilation is the z.compile(schema) function added in Zod 4.5. It walks a schema once and generates a flat JavaScript validator with new Function, used as a fast path for valid input. Invalid input falls back to the standard parser, so errors stay identical.
No, it cannot generate code under a policy that blocks new Function. Zod's documentation says the schema then comes back uncompiled, so parsing still works at standard speed. Zod 4.6 added z.withParser() for installing a parser generated at build time instead.
Zod 4.5 retains 784 bytes for a bare z.string() against 7.5 kB in 4.4.3, which is 9.8x less. Across Zod's 27-row table the saving runs from 2.0x for an empty object to 9.8x, with a 10-key object at 7.5x. It needs no code change.
Zod 4.5 made three behaviour changes. z.iso.datetime() now requires seconds, string length bounds count Unicode code points instead of UTF-16 units, and object and record parsers always drop a __proto__ key. Zod's post warns that schemas may now reject input they used to accept.
Zod's documentation lists async refinements, transforms and checks, z.xor(), recursive schemas, z.coerce.*, checks with a custom when, and .catch() with a callback. Inside a container the unsupported child runs on the standard parser, while a union with an unsupported member falls back entirely.
Upgrade to 4.6 if you parse recursive schemas in a long-lived process. Zod 4.5 held the input and output of the last parse, which caused an out-of-memory failure on a lint run. Zod reports one parse of a 29k-node tree dropping from 10.1 MB to 2.2 MB retained.
