Superintelligence regulation: what is law, what is proposed
Superintelligence regulation compared: the EU AI Act is law with dates, a 10^24 FLOP training cap is a proposal. What binds you, and what does not.
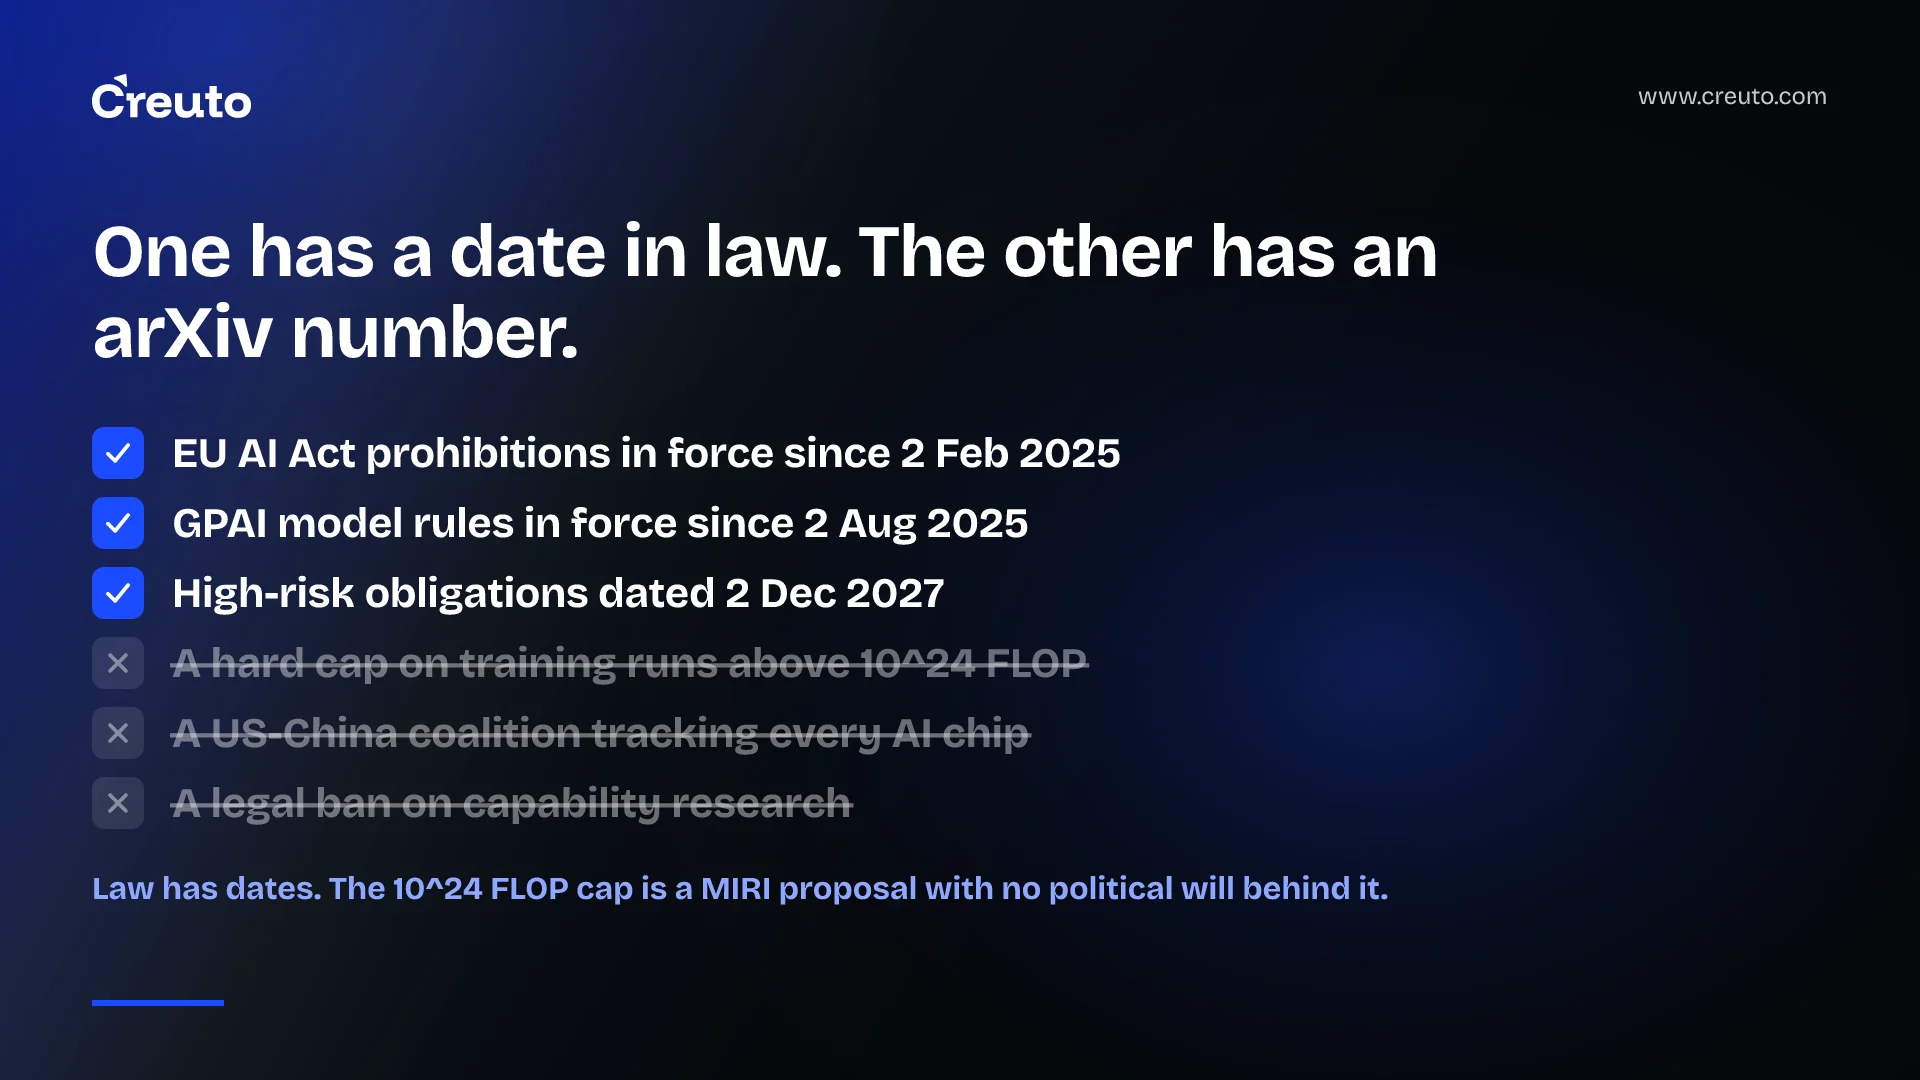
No law anywhere regulates superintelligence. The most detailed proposal for superintelligence regulation currently in circulation is an arXiv report by four researchers at the Machine Intelligence Research Institute, revised on 8 May 2026, which would ban any AI training run above 10^24 FLOP and track every AI chip on earth. It is a proposal. What is binding on your company is the EU AI Act, and that has dates.
The distinction matters because the two get blurred constantly. A paper describing a US–China treaty is not a regulation you can be fined under. An EU regulation with an application date of 2 August 2026 is. This post separates them, explains the mechanisms in the proposal properly, and ends with the obligations you can actually put in a compliance plan.
Superintelligence regulation today: the EU AI Act, and nothing else
There is no statute, treaty or binding instrument anywhere that names artificial superintelligence and restricts it. The closest thing to frontier-AI law in force is the EU AI Act, which the European Commission states entered into force on 1 August 2024 and became applicable on 2 August 2026. Its obligations arrive in stages, and those stages are the only dated frontier-AI compliance deadlines that exist.
| Date | What applies | Status |
|---|---|---|
| 2 February 2025 | Prohibitions on certain AI practices; AI literacy requirements | In force |
| 2 August 2025 | General-purpose AI model rules, governance, penalties; notified bodies | In force |
| 2 August 2026 | Remainder of the Act applies, including transparency obligations | Applicable |
| 2 December 2026 | Synthetic content transparency compliance deadline | Upcoming |
| 2 August 2027 | GPAI providers placed on the market before 2 August 2025 must comply | Upcoming |
| 2 December 2027 | High-risk obligations for Annex III systems apply | Upcoming |
Those dates come from the AI Act implementation timeline and the Commission's own framework page, which puts high-risk obligations as “starting on 2 December 2027”. Notice what is absent: no cap on training scale, no chip register, no prohibition on capability research. The Act regulates uses and model transparency. It does not try to stop anyone building a more capable model.
The proposal: two FLOP thresholds and a chip-tracking regime
Aaron Scher, David Abecassis, Peter Barnett and Brian Abeyta propose something far more aggressive. Their agreement, described in “An International Agreement to Prevent the Premature Creation of Artificial Superintelligence”, centres on a coalition led by the United States and the People's Republic of China, with both as the initial members of an Executive Council.
The operative mechanism is two compute thresholds. Training runs above the Strict Threshold of 10^24 FLOP would be prohibited outright. Runs between the Monitored Threshold of 10^22 FLOP and the Strict Threshold would need approval and monitoring by coalition authorities. Anything below 10^22 FLOP needs neither.
That first number is startling once you place it. The authors state the Strict Threshold sits below the scale of models already shipped, naming DeepSeek-R1 at roughly 4×10^24 FLOP and gpt-oss-120B at roughly 5×10^24 FLOP as examples trained “only slightly above” it. They chose it deliberately as a buffer against algorithmic progress. For comparison, the EU AI Act's general-purpose AI regime does not try to forbid a training scale at all.
Second, the agreement prohibits a defined category of dangerous research: work that would make AI systems more capable or more efficient to train at a fixed compute budget, in pre-training, post-training or inference. The authors explicitly keep the door open to extending it beyond machine learning to “connectomics, brain-inspired AI, fast genetic algorithms, GOFAI” if those paradigms start to look like a route to superintelligence.
How would an AI treaty be verified?
Verification is the part the authors treat as load-bearing, because the agreement assumes a low-trust environment in which neither superpower takes the other's word. Their answer is to make AI chips the unit of account.
- Locate existing chips through supply-chain tracking, mandatory reporting, state intelligence, open-source intelligence, power-consumption monitoring, challenge inspections and whistleblower programmes.
- Track new chips by exploiting a concentrated supply chain: the report notes that around 90 percent of advanced logic chips are fabricated by TSMC and that EUV lithography machines are made exclusively by ASML.
- Monitor chip use to distinguish inference on existing models from training of new ones, initially through ongoing physical access by inspectors, later through tamper-resistant on-chip mechanisms.
- Cap concentration by prohibiting clusters larger than 16 H100-equivalents outside monitored facilities — roughly $500,000 of hardware at 2025 prices.
The authors are candid about what that threshold does and does not achieve. By their own arithmetic, 16 H100s at FP8 and 50 percent utilisation would reach the Monitored Threshold in 7.3 days but would need two years to reach the Strict Threshold. Undeclared chips could get you into the monitored band; they would not realistically get you to a prohibited run.
What the authors say could defeat their own proposal
This is the paragraph most coverage skips, and it is the one an engineering leader should read. The report's own abstract states that the proposal “would be technically sufficient to forestall the development of ASI if implemented today, but advancements in AI capabilities or development methods could hurt its efficacy.”
The body is more specific. Citing historical trends, the authors write that the number of operations needed to train an AI to a given capability level drops by a factor of three each year, which means the cluster size that must be monitored to hold verification constant also falls by three each year. Their conclusion: “If such trends are not interrupted, widespread consumer computers would eventually become dangerous, and it would be insufficient to monitor data center AI chip use.” They add that they are unsure consumer computers could be monitored, and that doing so would not be morally desirable.
They name two further failure modes: a single architectural jump — they cite an estimate that the transformer alone delivered a 7.2× reduction in operations, about two years of progress — arriving with little warning, and a non-deep-learning paradigm succeeding with far less compute, against which the agreement “would not be robust”. And they say plainly that “there does not yet exist the political will to put such an agreement in place.”
So the honest summary is this: the researchers who designed the most concrete superintelligence ban on offer believe it works if enacted now, and gets weaker every year it is not.
What is compute-based regulation, and what binds you now
Compute-based regulation means drawing the regulatory line at training scale rather than at what a system is used for. It is attractive because FLOP is countable and chips are physical, and it is fragile for exactly the reason above: the compute needed for a given capability keeps falling.
If you are shipping AI features into the EU, none of the treaty mechanics apply to you. Your obligations are the dated ones in the table: transparency for synthetic content by 2 December 2026, general-purpose AI model duties already live since August 2025, high-risk duties from 2 December 2027 for Annex III systems. Confirm your own classification with your legal adviser rather than from a blog post, including ours.
What we do tell clients is that the engineering work the two regimes demand overlaps more than it looks. Both want you to know which model version served which request, what data trained or fine-tuned it, who approved a deployment and what the system was permitted to do. In the systems we build, that is provenance logging, model registries and role-based approval gates — the same substrate we describe in our work on enterprise AI agent governance. Teams that put it in before a deadline forces them spend the deadline filling in fields, not rebuilding.
The other reason to build it now is that capability evaluations are already producing consequences without any treaty. When a frontier model ships with a published cybersecurity risk rating, as we covered in the first Critical rating issued for a frontier model, procurement teams start asking which model you used and why. That question arrives long before an international agreement would.
Who regulates frontier AI, in practice
Today: the European Commission and national competent authorities under the AI Act, plus whatever sectoral regulator already governs your industry. Not an international body, because none exists with jurisdiction over training runs. The MIRI proposal would create one — an Executive Council with a coalition-level tracking body — and the authors put its arrival behind a political-will condition they say is unmet.
If you are deciding how much governance to build into an AI product this quarter, build for the AI Act dates and design so that a future compute or provenance requirement is a configuration change rather than a rewrite. That is a normal architecture decision, and it is the kind of constraint we plan for in AI engineering work and in the custom software we build around it.
Frequently asked questions
No. As of October 2026 no statute or treaty anywhere names artificial superintelligence and restricts it. The most detailed proposal is a Machine Intelligence Research Institute report revised in May 2026, and its authors state the political will to enact it does not yet exist.
The MIRI proposal would prohibit AI training runs above 10^24 FLOP, require approval and monitoring for runs above 10^22 FLOP, and legally prohibit research that advances AI capabilities at a fixed compute budget or that undermines the agreement's own verification methods.
By treating AI chips as the unit of account: locating existing chips through supply-chain tracking and intelligence work, tracking new production through a concentrated supply chain, monitoring chip use to separate inference from training, and banning clusters above 16 H100-equivalents outside monitored facilities.
Compute-based regulation sets the regulatory line at training scale, measured in floating-point operations, rather than at how a system is used. It is attractive because compute is countable, and fragile because the compute needed for a given capability keeps falling each year.
In the EU, the European Commission and national competent authorities under the AI Act, alongside existing sectoral regulators. No international body has jurisdiction over training runs. The proposed coalition Executive Council would be the first, and it does not exist.
Prohibitions and AI literacy duties have applied since 2 February 2025 and general-purpose AI model rules since 2 August 2025. The remainder of the Act applies from 2 August 2026, synthetic content transparency from 2 December 2026, and Annex III high-risk obligations from 2 December 2027.
